1. The problem is not just compute time
Request validation, fingerprint computation, queue admission, state transitions, atomic writes, crash recovery and error reporting are ordinary software behaviours. None of them should need a diffusion model to be verified.
If every test loads the weights, the development loop becomes slow, expensive and ambiguous. A failure can come from the network, the weights, memory or the orchestration, without its cause being immediately visible. The solution is to isolate the minimal capability expected from the compute: receive a resolved job, produce an image and preserve its provenance.
2. Two paths converge on the same contract
The HTTP server and the sweep tool do not follow exactly the same path. The API creates durable jobs, puts them in a queue and lets a single worker execute them. The sweep builds a list of manifests directly and passes them to the runner after skipping the outputs that already exist.
HTTP request                    sweep file
     ↓                               ↓
validation, job, queue         validation, planning
     ↓                               ↓
   worker                       sweep executor
     └──────────── manifest ───────────┘
                         ↓
                  BaseRunner.run()
                    ↙         ↘
                  stub          MFLUX
The manifest contains the job type, the profile, the prompt, the seed, the dimensions, the parameters and, depending on the case, a parent image or the mask settings. The runner chooses neither the next identifier, nor the resumption policy, nor the output path: those decisions have already been made when it receives the manifest.
The shared class handles dispatch, measurement, writing the PNG and the sidecar. A backend only implements the generation operation:
class BaseRunner(ABC):
    @abstractmethod
    def generate(
        self, *, prompt, seed, steps, guidance, width, height,
        image_path=None, image_strength=None,
    ) -> Image.Image:
        """Produce a PIL image."""

    def run(self, manifest: Manifest) -> Result:
        started = time.perf_counter()
        image, metrics = self.render(manifest)
        duration = round(time.perf_counter() - started, 3)
        atomic_image(Path(manifest.output), image, format="PNG")
        sidecar = self.sidecar(manifest, metrics, duration)
        atomic_json(Path(manifest.metadata), sidecar)
        return Result(
            Path(manifest.output), Path(manifest.metadata), duration, metrics
        )
The real code also measures the duration and checks that the manifest's profile is the one served by the process. The important point lies elsewhere: the shared writing and provenance logic cannot diverge between the stub and MFLUX.
3. A stub engine that produces information
A useful stub does not return an empty constant. It builds a gradient from the prompt, the seed, the dimensions and the generation parameters, then adds a readable caption. For an edit, it also blends the parent image into the result. A stub contact sheet therefore remains usable to inspect a sweep and its lineage.
material = f"{prompt}|{seed}|{steps}|{guidance}|{width}x{height}"
rng = np.random.default_rng(_stable_seed(material))
image = _gradient(width, height, rng)

if image_path is not None:
    source = Image.open(image_path).convert("RGB")
    source = source.resize((width, height), Image.Resampling.LANCZOS)
    image = Image.blend(source, image, 0.45)
Two identical runs produce the same PNG byte for byte, and two different seeds produce different images. This identity does not extend to the sidecar: its timestamp and duration naturally change from one run to the next.
The runner's name is part of the fingerprint. A placeholder created by the stub therefore cannot take the name or the cache entry of a future MFLUX output.
The stub also has deliberate limits. It does not reproduce the real engine's
sensitivity to every parameter, image_strength in particular, and its
determinism says nothing about MFLUX's determinism across machines. It verifies
the behaviour of the orchestration, not the physics of the model.
4. Do not load what was not asked for
The decoupling would be incomplete if importing the package still loaded MLX, MFLUX or Torch. The heavy dependencies are therefore optional extras, and the real runner is only imported when it is explicitly selected:
def build_runner(profile, name):
    if name == "stub":
        from imagegen.runners.stub import StubRunner
        return StubRunner(profile)
    if name == "mflux":
        from imagegen.runners.mflux import MfluxRunner
        return MfluxRunner(profile)
    raise ValueError(f"unknown runner {name}")
The same principle applies to segmentation. The segmenter is only built on the first masked job. Tests use a stub geometric segmenter; CLIPSeg, Transformers and Torch are not needed to test crops, deterministic noise and recomposition.
5. What becomes testable without a model
This separation covers, among other things:
- strict manifest validation;
- sweep planning and resumption;
- deduplication by fingerprint;
- HTTP responses and queue depth;
- the
queued,running,done,failedandinterruptedstatuses; - the append-only journal and its replay after a restart;
- contact sheet generation;
- crops, stub segmentation and recomposition;
- the invariant that requires a zero delta outside the mask.
A stub test expresses the determinism contract directly:
def test_the_same_job_twice_is_byte_identical(tmp_path, profile):
    first = make_manifest(tmp_path, output=tmp_path / "a.png")
    second = make_manifest(tmp_path, output=tmp_path / "b.png")
    run(profile, first)
    run(profile, second)
    assert first.output.read_bytes() == second.output.read_bytes()
Each write is atomic on its own: every temporary file is renamed on the same file system once it is complete. A reader therefore never sees a half-written PNG or JSON file. This is not, however, a transaction spanning the PNG and its sidecar: a crash between the two writes can leave a complete image without its metadata.
6. What only the real engine can confirm
A test double cannot prove:
- that the checkpoint and a replacement encoder actually load;
- that LoRAs are applied in the right order;
- that the architecture and the adapters are compatible;
- the quality of segmentation on real images;
- memory consumption and throughput;
- the visual quality of the result.
These properties belong to a small suite of hardware smoke tests. A successful image does not replace the software tests; it only validates the real inference path used to produce it.
7. A reproducible check
Revision 4720537
of the repository contains 144 tests. They were run in a fresh Python 3.14.4
environment containing only the standard dependencies and the dev extra. A
check with importlib.util.find_spec confirmed that Torch, MFLUX, MLX and
Transformers were absent.
UV_PROJECT_ENVIRONMENT=/tmp/imagegen-dev-only \
  uv sync --extra dev

UV_PROJECT_ENVIRONMENT=/tmp/imagegen-dev-only \
  uv run python -c \
  "import importlib.util; print({n: importlib.util.find_spec(n) is not None for n in ('torch', 'mflux', 'mlx', 'transformers')})"

UV_PROJECT_ENVIRONMENT=/tmp/imagegen-dev-only uv run pytest -q
UV_PROJECT_ENVIRONMENT=/tmp/imagegen-dev-only uv run ruff check src tests bench
On 14 September 2026, this procedure produced the following result:
{'torch': False, 'mflux': False, 'mlx': False, 'transformers': False}
144 passed, 2 warnings in 2.97s
All checks passed!
The two warnings come from deprecations in the FastAPI and Starlette test tooling; they signal neither a skipped test nor a failure. Installing the dependencies may require network access, but running this suite does not once the environment is built.
A minimal real smoke test uses a separate environment:
UV_PROJECT_ENVIRONMENT=/tmp/imagegen-mflux-smoke \
  uv sync --extra dev --extra mflux

UV_PROJECT_ENVIRONMENT=/tmp/imagegen-mflux-smoke \
  uv run imagegen-sweep sweeps/example.json \
    --profile plain-4b \
    --runner mflux \
    --limit 1 \
    --out /tmp/imagegen-real-smoke-20260914
On a macOS arm64 machine with MFLUX 0.19.1 and MLX 0.32.2, the runner loaded
the public checkpoint mlx-community/flux2-klein-4b-4bit in 3.5 seconds. It
then produced, in 24.65 seconds, a 768 × 1024 pixel image, its manifest, its
sidecar and the sweep index:
runner mflux ready in 3.5s
[1/1] harbour seed 1  harbour_45b9d36c0e_seed1.png  24.65s
1 produced, 0 failed
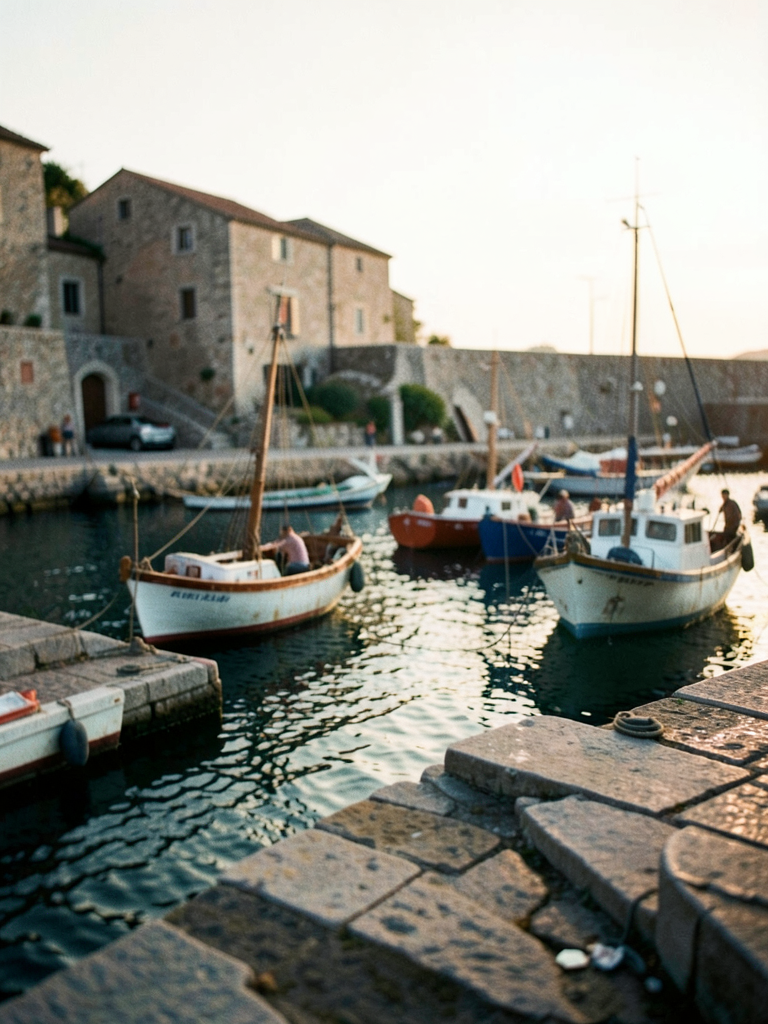
Raw smoke test output, with no retouching and no selection among several
variants. The sweep planned seven images, but --limit 1 ran only one.
The manifest preserves the inputs to the computation. The sidecar adds the effective identity of the engine and the measurements of the run. Both complete artifacts are shown below.
Resolved manifest
{
  "kind": "generate",
  "job_id": 0,
  "profile": "plain-4b",
  "prompt": "cinematic photograph, shallow depth of field a stone harbour at first light, fishing boats",
  "seed": 1,
  "steps": 4,
  "guidance": 1,
  "width": 768,
  "height": 1024,
  "input_image": null,
  "image_strength": null,
  "mask": null,
  "output": "/tmp/imagegen-real-smoke-20260914/harbour_45b9d36c0e_seed1.png",
  "metadata": "/tmp/imagegen-real-smoke-20260914/harbour_45b9d36c0e_seed1.metadata.json",
  "diagnostics": null
}
Full sidecar
{
  "job_id": 0,
  "kind": "generate",
  "runner": "mflux",
  "prompt": "cinematic photograph, shallow depth of field a stone harbour at first light, fishing boats",
  "prompt_sha256": "eacd87a67ca4d826eff3aa9e842d478ac9d0a5a003860ac4ab2bca79e25ff522",
  "seed": 1,
  "steps": 4,
  "guidance": 1,
  "width": 768,
  "height": 1024,
  "input_image": null,
  "mask": null,
  "provenance": {
    "profile": "plain-4b",
    "engine": "klein-4b-stock",
    "checkpoint": "mlx-community/flux2-klein-4b-4bit",
    "model_config": "flux2_klein_4b",
    "encoder": null,
    "adapters": [],
    "bake": false
  },
  "metrics": {},
  "duration_s": 24.65,
  "created_at": "2026-09-14T01:23:28.492146+00:00"
}
The sidecar confirms the mflux runner, the plain-4b profile, four steps, a
guidance of 1.0 and no adapter. This smoke test therefore verifies neither
LoRAs, nor the replacement encoder, nor CLIPSeg: each one requires an
additional real test case.
8. Adding another engine
A new backend must load its resources and implement generate(...) to return a
PIL image. Manifest handling, masking, writes and provenance stay in the shared
class; the API, the queue and the sweep planner do not have to change.
This promise does, however, come with a condition: the contract must not be implicitly modelled on MFLUX. Adding a second real engine would be the strongest test of its generality. Until then, the stub mainly proves that the orchestration is not coupled to loading MFLUX.
9. Conclusion
A narrow boundary between orchestration and inference transforms the testability of a generative platform. The stub makes tests of software behaviour fast and deterministic; the real engine focuses on the hardware and visual properties that no double can simulate.
This separation does not only serve testing. It also prepares for swapping a backend and for running inference in a separate process. Distributing the compute across several machines still requires making transport, capabilities and network failures explicit: that is the next step, not a property already provided by the local contract alone.